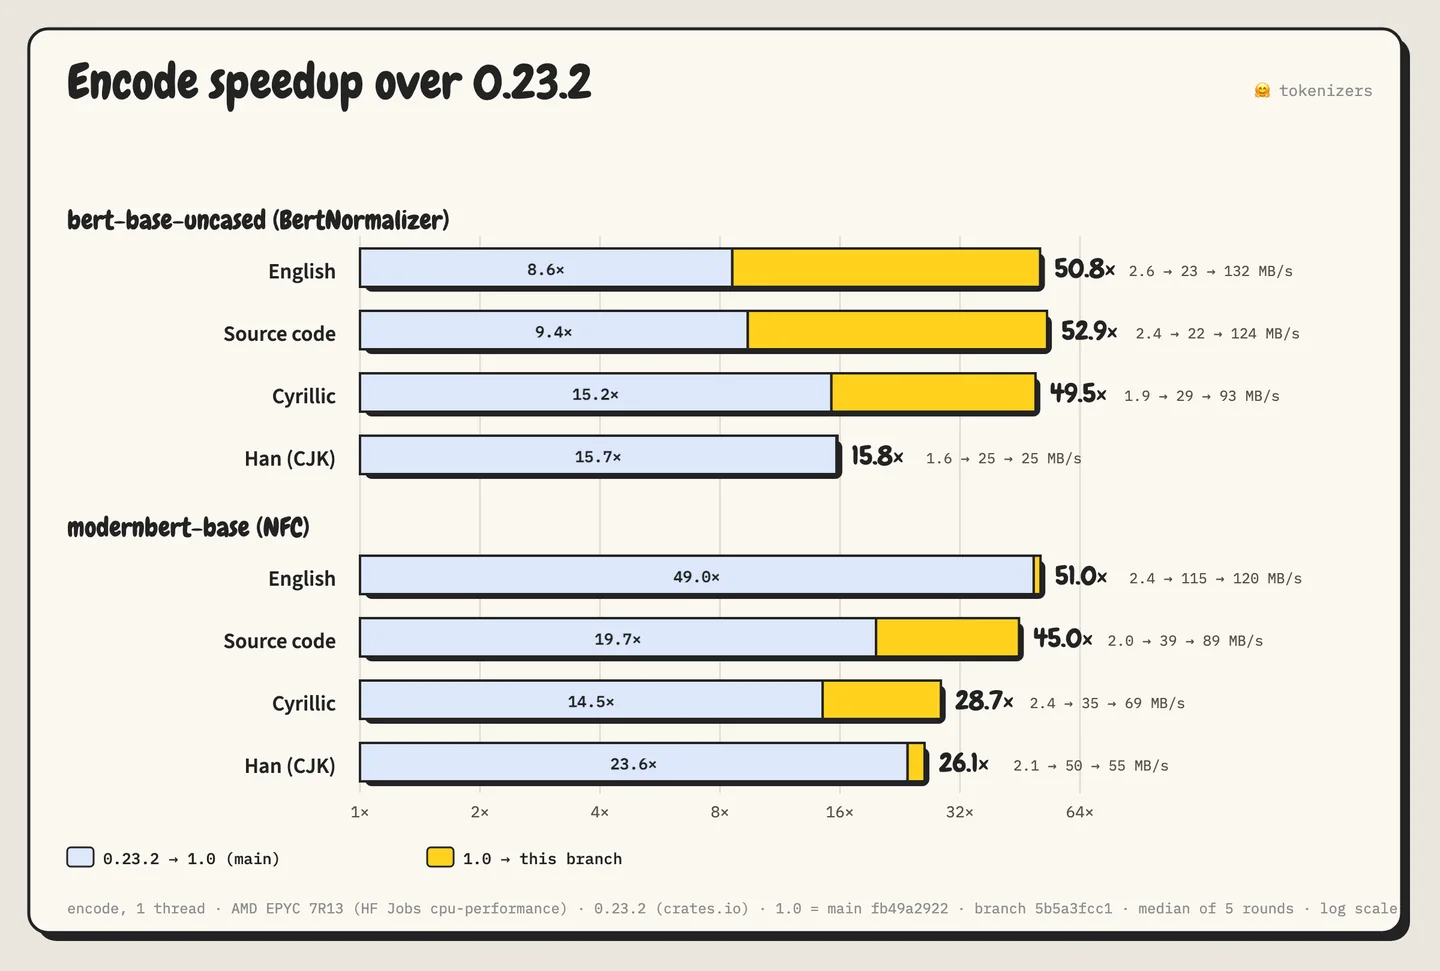
The reported gain concerns the step that turns text into tokens. Hugging Face's authors compare encoding throughput with tokenizers 0.23 and report a total BERT tokenization speedup of about 50× under their protocol, including another improvement of up to 5.7× described in the post.
The technical work isolates normalization costs and ASCII paths in particular. BERT and WordPiece still serve embeddings, reranking and classification, so preprocessing can remain relevant even where the final application is not a text generator. How much a given pipeline benefits depends on its corpus, characters, languages and actual bottlenecks.
At the time of the October 15 article, the changes are still in a pull request and version 1.0.0 is being prepared. Code and a reproducer are public, but this is not a claim that the optimizations already ship in a stable release. The results were not reproduced here, and a 50× gain in tokenization is not a 50× gain in model inference or end-to-end latency.